Two minutes to a running agent
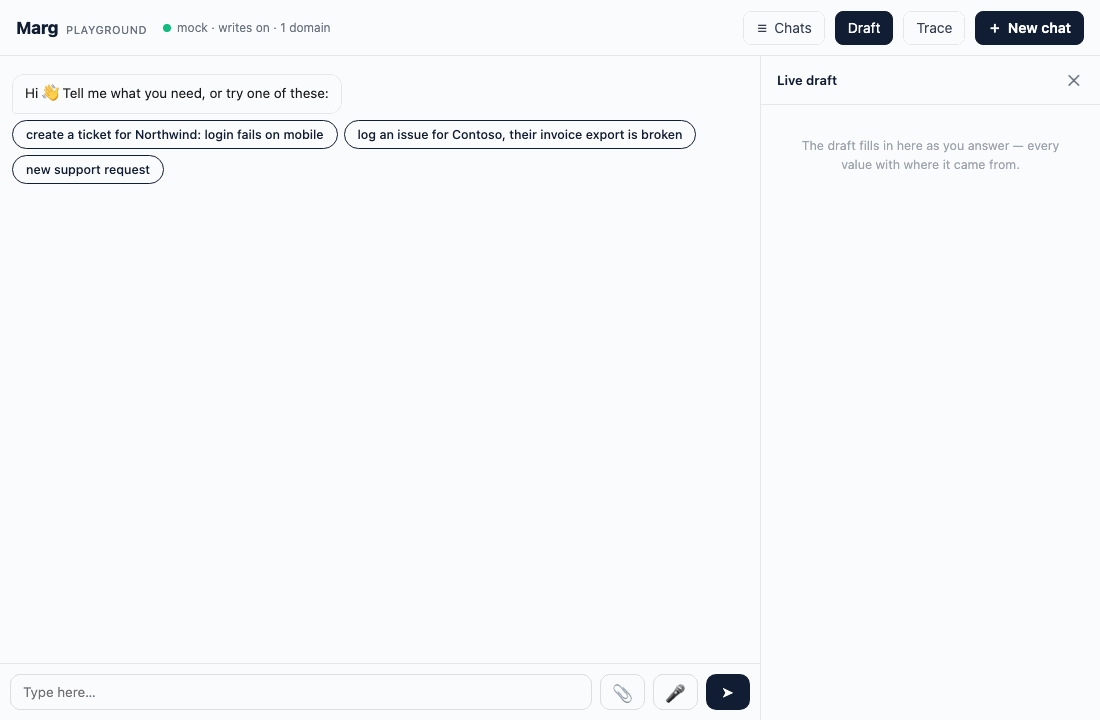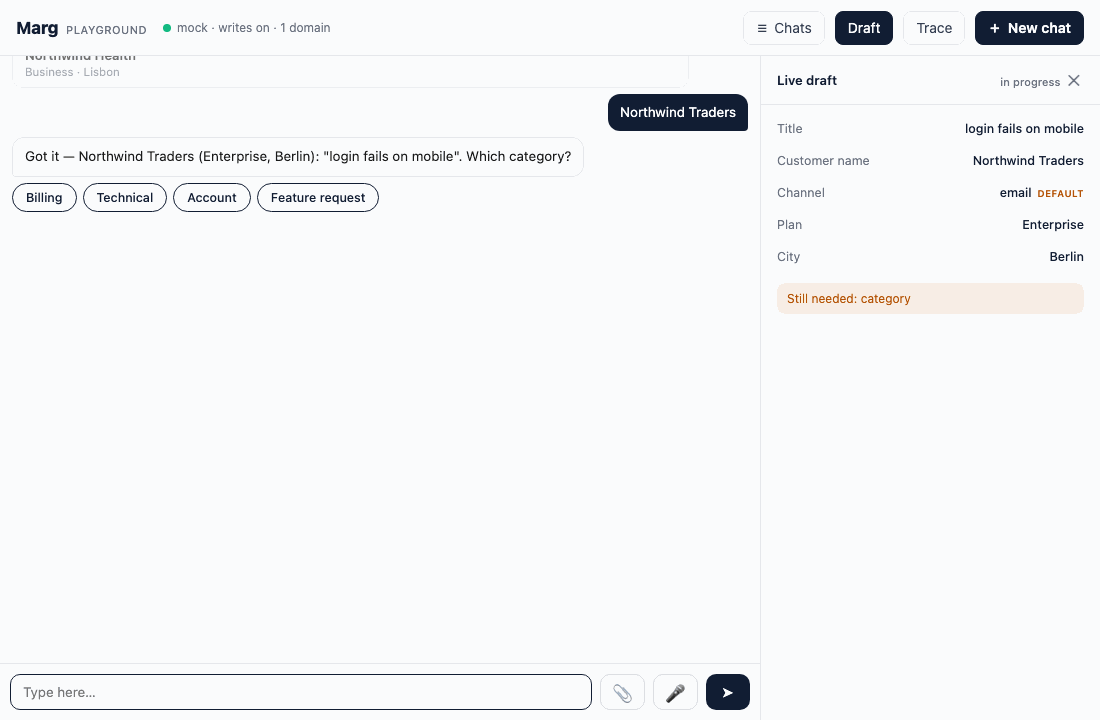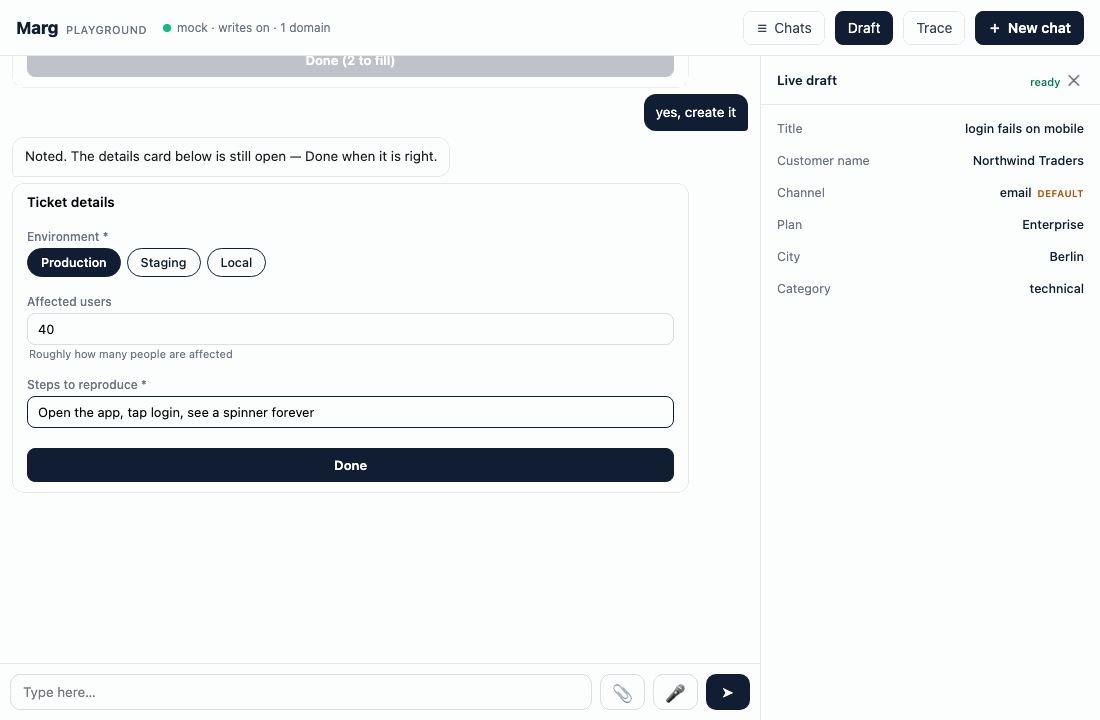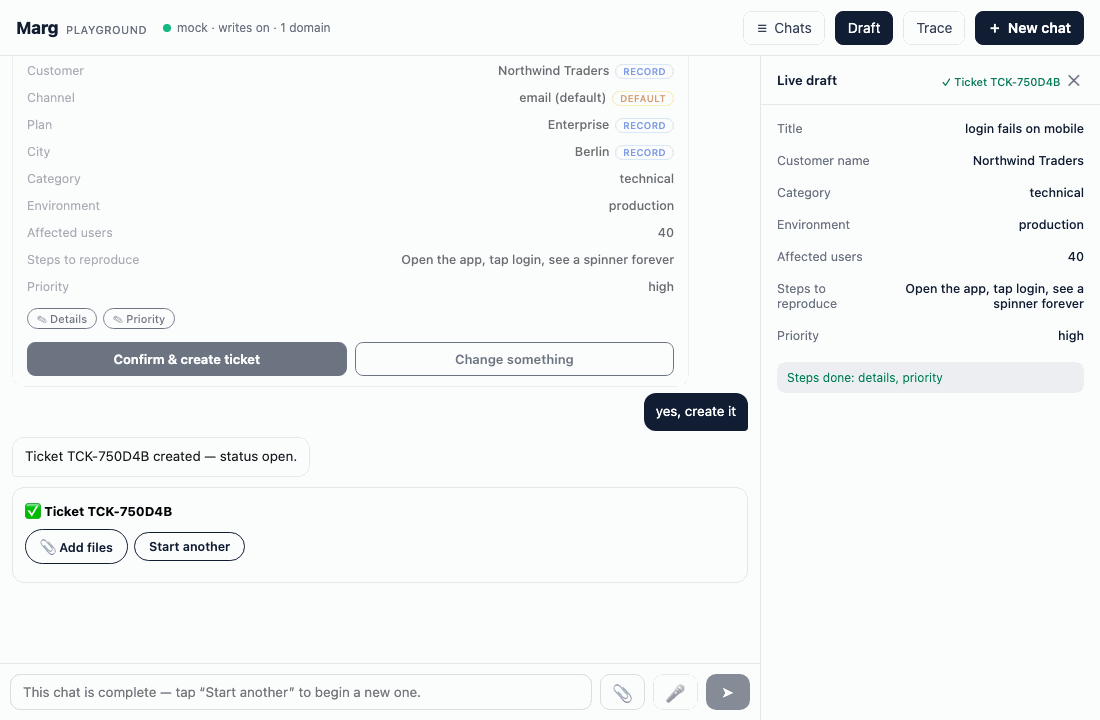
Open the playground and type "ticket for Northwind: login fails on mobile". A customer picker, category chips, a details card the runtime draws and reads, priority chips, a summary with Change something, the create. Switch to a real model by editing one line in .env (LLM_CHAIN=anthropic, LLM_CHAIN=openai,anthropic, LLM_CHAIN=ollama); nothing else changes.
Measured in the field
The numbers that justified the design, from the production agent Marg was extracted from.
| Observation | Result |
|---|
| Questions a model-led prompt skipped, despite the rule | 25 to 50 percent of turns |
| List items a model attested that the user never said | 1 chat in 64 |
| Typed replies a leading-word reader mis-read as a bare yes or no, blind corpus of 521 | 235 |
| The same corpus, read by the whole content | 0 |
ui blocks malformed around the fence in production traffic | about 1 in 40, all parsed |
The model must never read "yes" tells the story behind the third and fourth rows.
Is Marg for you?
Use Marg when your agent must complete a transaction, not only answer; when the result is published under a real user's name; when several specialist agents sit behind one entry point; when you need to prove behaviour before and after every change without burning model credits; when you are going to run it yourself.
Look elsewhere when you want a general library for arbitrary agent graphs, your bot only answers and never writes, you want a hosted platform, or your stack must be Python end to end. Marg and other frameworks says where the line is.
Frequently asked questions
Which models can I use?
Anthropic natively, and any OpenAI-compatible endpoint: OpenAI, Gemini, Vertex AI, Azure OpenAI, Bedrock, Ollama, vLLM, LiteLLM, Groq, Mistral, DeepSeek, Fireworks, Together, OpenRouter, xAI, Cohere, Hugging Face, Cerebras, Perplexity, NVIDIA, one environment line each (Models). A chain of endpoints with failover and a circuit breaker is one line, LLM_CHAIN=openai,anthropic. The scripted mock model runs everything with no key.
What makes Marg different from an agent framework?
Marg is opinionated about one job shape, collect → validate → confirm → write, and puts the costly moments in the runtime instead of the prompt. The reader that reads "yes" by the whole message, the three-fold write gate, and the offline eval gate exist because their absence cost something in production. The pattern explains each rule and the failure it answers.
How do I connect my backend?
Through an MCP tool server, in any language: reads, and the triad validate_*, preview_*, create_*. The example domain's server is the reference; probe the real backend before trusting its documentation. A new domain.
How do I prove it still works after a change?
Run the gate: unit tests, the OpenTelemetry check, the scaffold check, the real-write e2e, and the example suite against a writes-off gateway, all on the mock model. Every red is classified before it is fixed. Evals.
How do I deploy it?
One non-root image, Compose profiles for stores, observability, decisions and the TLS edge, and a Render blueprint for a demo. Deploy, then the production checklist.